 AsrielNetworks
Free plan: how to use it
Everything on the Free tier, module by module: what each screen is for in plain terms, when to open it, how to work it, and what the numbers mean. Free runs every built-in detection rule; it holds back the analysis layers above it, which are listed at the end.
The first hour
- Create the workspace Sign up with your company and role; the workspace, your membership and the subscription are provisioned on the spot. Get the product from the products page; the three questions there set your defaults.
- Connect one application Open Connect AI: register the model deployment, mint a credential scoped to your application and agent, and point the application at AsrielNetworks (SDK, gateway or your own emitter).
- Watch the Overview Within a minute of the first request the tiles move and the attack graph shows the stages. If nothing arrives, Connect AI's third step tells you what it is waiting for.
- Set who gets told In Settings → AI Incident Response set severities and the escalation chain; add the channels your plan includes.
- Open your first incident Run one deliberately bad request through the connected application (a denied tool call is enough). Read it in AI Incidents: queue, investigation, evidence, response.
Overview
Overview
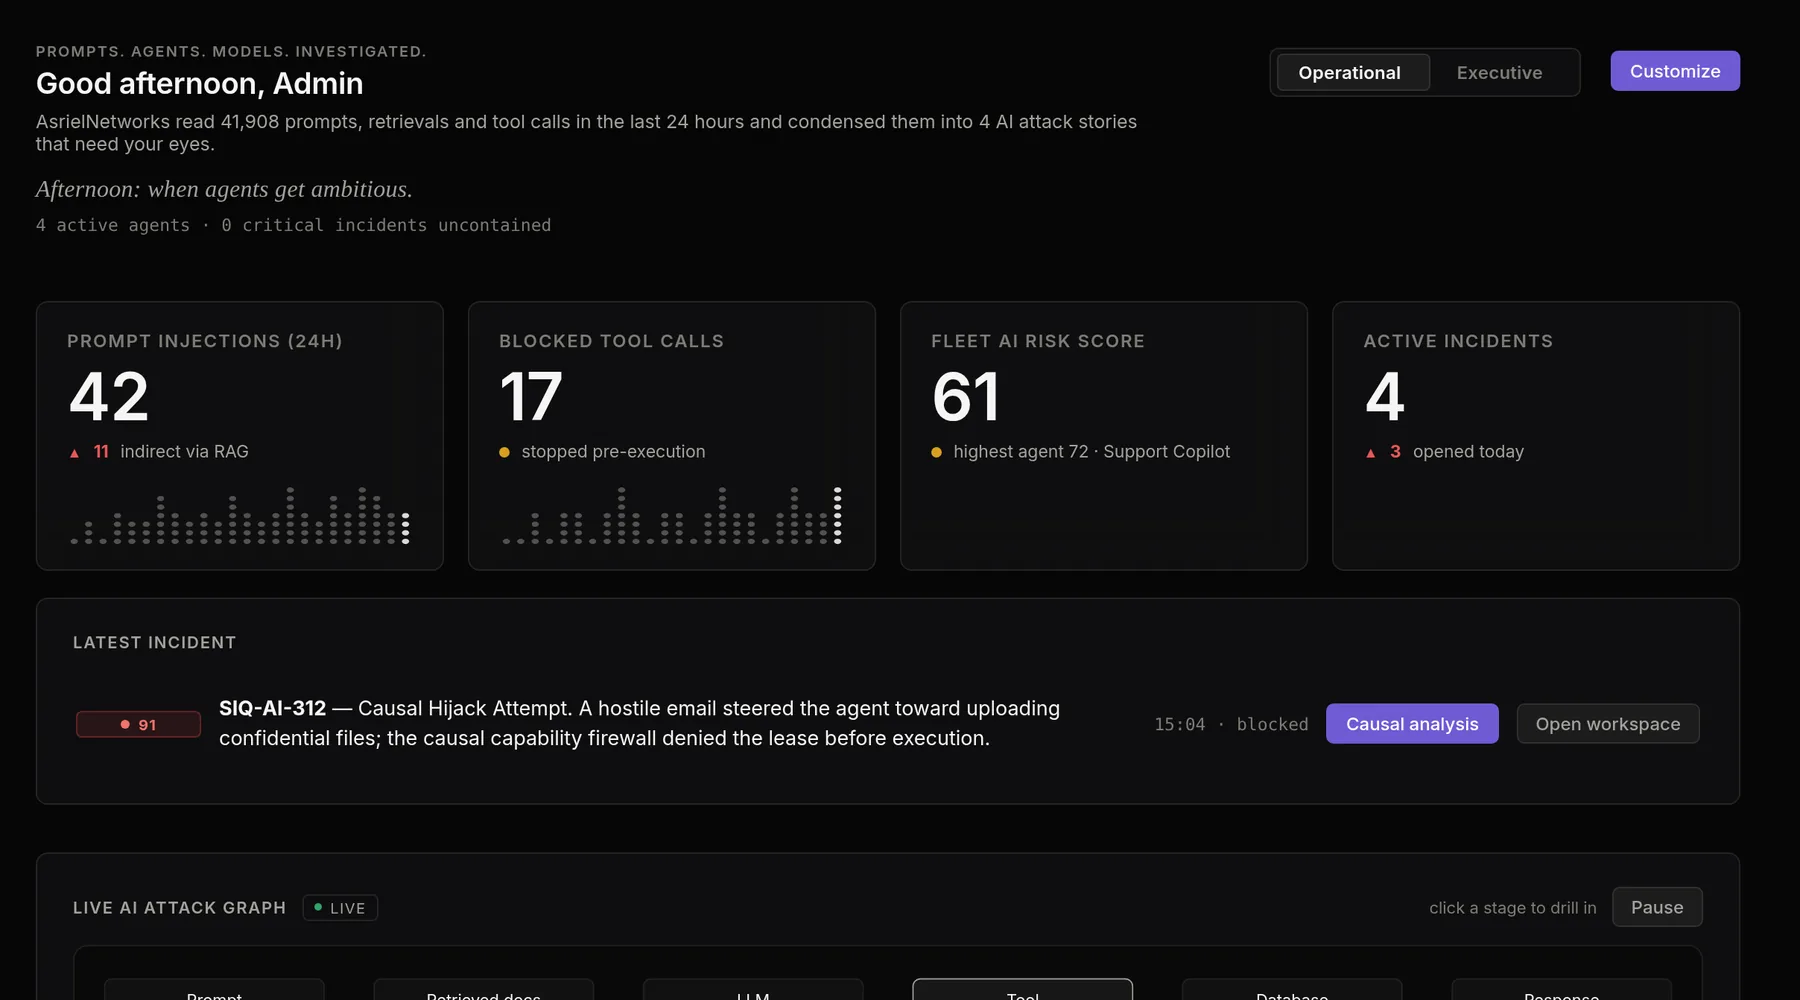
freeThe first screen after sign-in. It condenses everything the platform read in the last 24 hours into four numbers, the latest incident, and a live picture of where prompts are flowing.
Open it when: Start of a shift, after a deploy, or whenever someone asks “is anything wrong right now?”
How to use it
- Read the four tiles left to right: Prompt injections (24h), Blocked tool calls, Fleet AI risk score, Active incidents. Each carries a small delta and a sparkline; a rising sparkline with a flat incident count usually means detections are being contained before they become incidents.
- Open Latest incident when the badge is red. The two buttons take you into the incident workspace (Open workspace) or, on plans that have it, straight to the causal analysis.
- Use the Live AI attack graph to see the stages a request passes through (prompt, retrieved docs, LLM, tool, database, response) and where things are being refused or held. Click a stage to drill into the events behind it; Pause freezes the feed while you read.
- Switch Operational to Executive for the same data as a management summary. Customize lets you pick which tiles you see.
- The sentence under the greeting is generated from your own telemetry (how many prompts, retrievals and tool calls were read, how many incidents they produced). It is a status line, not a chat.
Reading the screen
- Fleet AI risk score is 0 to 100 across every agent; the tile names the agent that is pulling it up.
- Blocked tool calls counts calls the policy refused before execution; a call that executed and was flagged afterwards is a finding, not a block.
- Active incidents counts open incidents, not findings; several findings on one trace roll into one incident.
Investigate
AI Incidents
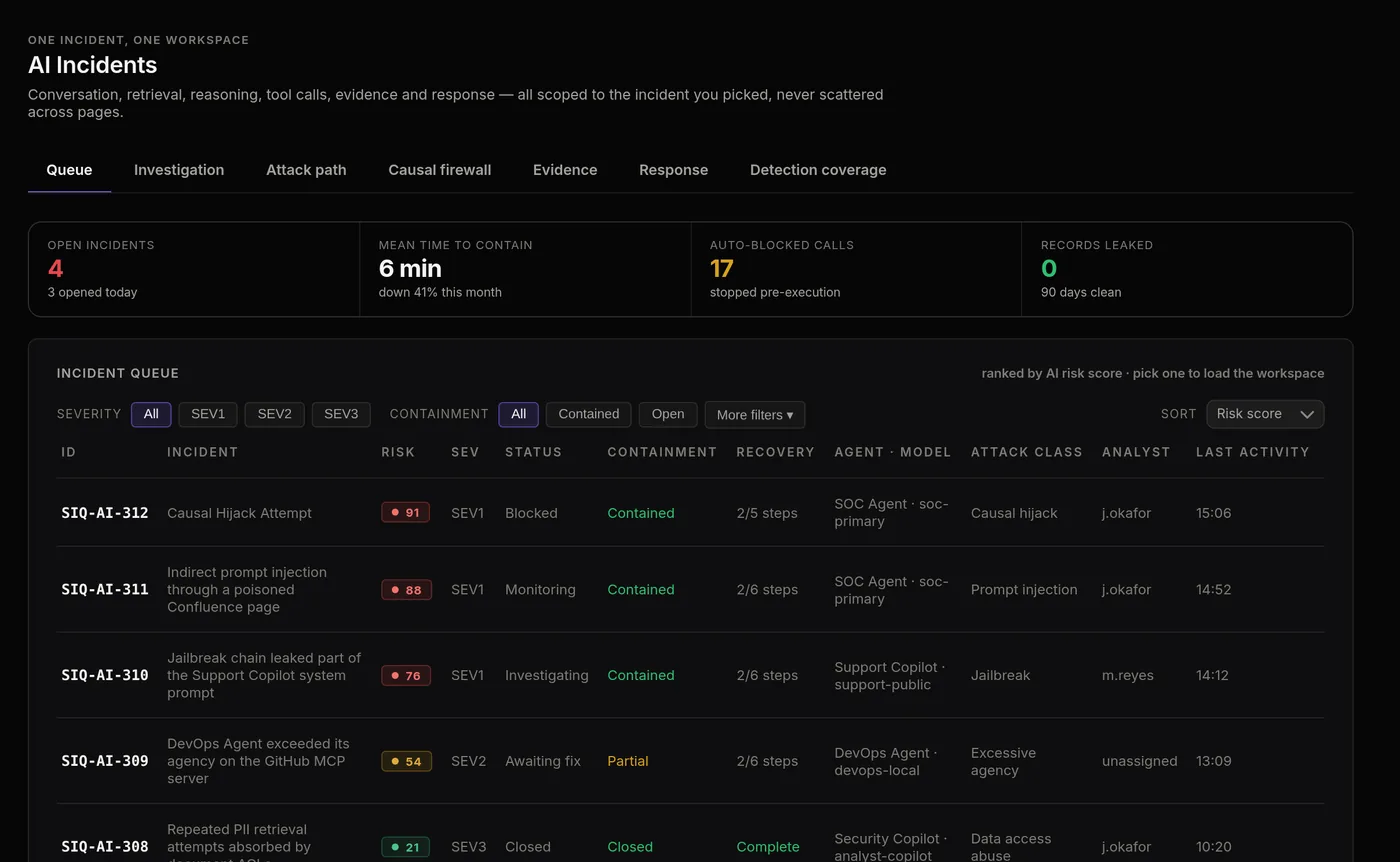
freeThe incident workspace. Every finding the detection engine raises lands here, correlated into an incident with a risk score, and everything about that incident is on one screen: the conversation, the retrievals, the tool calls, the evidence and what was done about it.
Open it when: Anything red on the Overview, an alert email, or the daily review of the queue.
How to use it
- In Queue, incidents are ranked by AI risk score. Filter by severity (SEV1 to SEV3) and containment (contained, open). The columns tell you the status, how far recovery has got (2/5 steps), which agent and model were involved, the attack class, and who is working it.
- Pick an incident to load the workspace. Investigation shows the trace in order: the prompt that started it, what was retrieved, what the model reasoned, what it proposed, what the policy decided, what executed. Findings are attached to the events that raised them.
- Evidence holds the sealed record: hashes of the events, the raw structured signals the detectors used, and the redaction state of each item. Sealed evidence cannot be edited or deleted; that is what makes it usable later.
- Response is where you act. Actions lists the response plan derived from the rules that fired (block a tool, revoke a credential, suspend an agent, quarantine a document); each shows whether it needs approval. Recovery tracks the steps to closure.
- Set the status as you go (investigating, contained, resolved) and assign an analyst; the queue and the Overview update immediately.
- Tabs that your plan does not include stay visible with a lock: Attack path and Detection coverage open on Pro, Causal firewall on Enterprise.
Reading the screen
- Risk is the incident's score (the highest severity, weighted by confidence and how far it got).
- Containment answers “can it still do harm?”; Status answers “are we done?”. An incident can be contained and still under investigation.
- Attack class is the detection category: prompt injection, excessive agency, data access abuse, supply chain, causal hijack.
Session Replay
freeA recorded session played back one frame at a time: prompt, retrieval, model, reasoning, guardrail, tool, and what the guardrail did about it. It is the same trace the Investigation tab shows, presented as a timeline you can step through.
Open it when: When you need to explain to someone else exactly how a bad outcome happened, or to check what the model saw at the moment it chose a tool.
How to use it
- Pick a session from the selector (incidents link straight to theirs).
- Use the transport controls: Play runs the chain at reading speed; the arrow buttons step one frame; the end buttons jump to the first or last frame.
- Each frame shows the event's kind, its structured data (for a tool call: the tool, its category, the policy decision), and any finding raised on it. A Blocked frame means the guardrail or policy stopped the chain there.
- The chain strip at the top (Prompt, Retrieval, LLM, Reasoning, Guardrail, Tool, Blocked, Response) is clickable: jump to the stage you care about.
Reading the screen
- Content shown is subject to your telemetry settings: if prompts are redacted at the source, the frame shows the structured signals and the redaction state, not the text.
- Reasoning frames are the model's own summaries where the runtime emits them; they are evidence of what was considered, not a transcript.
Prompt & Event Explorer
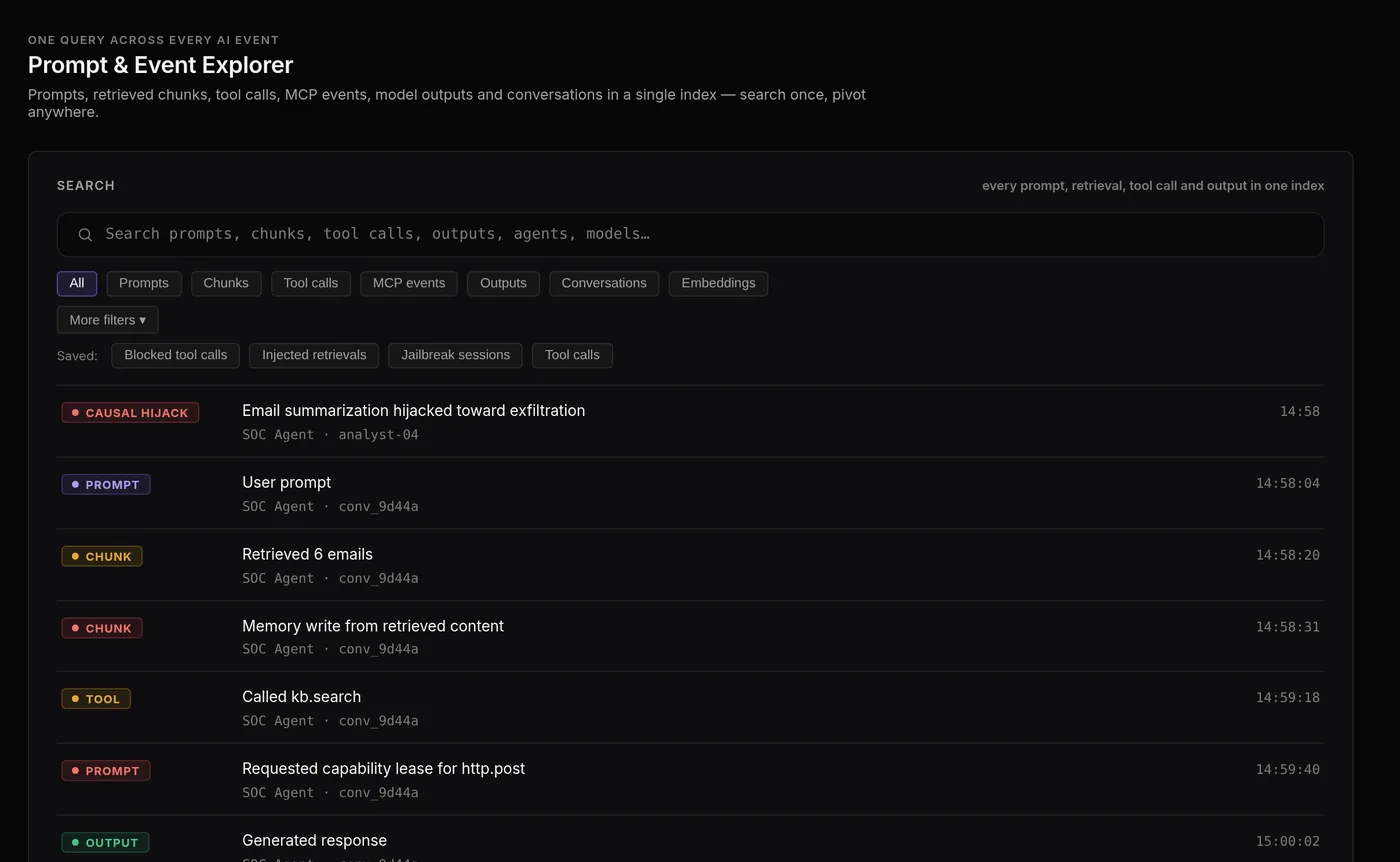
freeOne search box over every AI event: prompts, retrieved chunks, tool calls, MCP events, model outputs, whole conversations, even embeddings. Search once and pivot to the incident, the agent or the session.
Open it when: Hunting: “did any agent ever call http.post to that host?”, “which sessions retrieved this document?”, “show me every jailbreak attempt this week”.
How to use it
- Type a term. The index matches tool names, document ids, agent and session references, and the text of prompts and outputs that your telemetry settings allow to be stored.
- Narrow with the type chips: Prompts, Chunks, Tool calls, MCP events, Outputs, Conversations, Embeddings. More filters adds agent, model, time window and policy decision.
- Use the Saved searches (Blocked tool calls, Injected retrievals, Jailbreak sessions) as starting points, and save your own once a query proves useful.
- Each result row shows the event kind, its title, the agent and the session; click through to the session or the incident it belongs to.
Reading the screen
- Kinds are the platform's event vocabulary:
prompt.received,document.retrieved,tool.proposed,tool.denied,tool.execution.completed,response.deliveredand so on. - A row tagged with a finding badge (for example causal hijack) is an event a rule fired on.
Unified Graph
freeOne picture of how the organization's AI hangs together: which agent ran which prompt, on which model, what it retrieved, which tools and standing grants it holds, and which incidents came out of it.
Open it when: When a change is planned (“what depends on this MCP server?”) and when an incident needs context (“what else does this agent touch?”).
How to use it
- Choose a layer: AI estate (agents, models, tools, corpora and the grants between them) or Security evidence (the same nodes with findings and incidents attached).
- Pick the window: 1h, 24h or 7d. Edges only appear for relationships observed in that window, so the 7-day view is the honest map of what the estate really uses.
- Click a node to see what it connects to; the side panel lists the edges with their evidence (the events that proved the relationship).
Reading the screen
- A grant edge (agent to tool) is standing permission; a call edge is an observed use. An agent with grants it never uses is a good candidate for tightening.
- This page reads live relationships from the API; it has nothing to show until telemetry has arrived.
AI estate
AI Agents
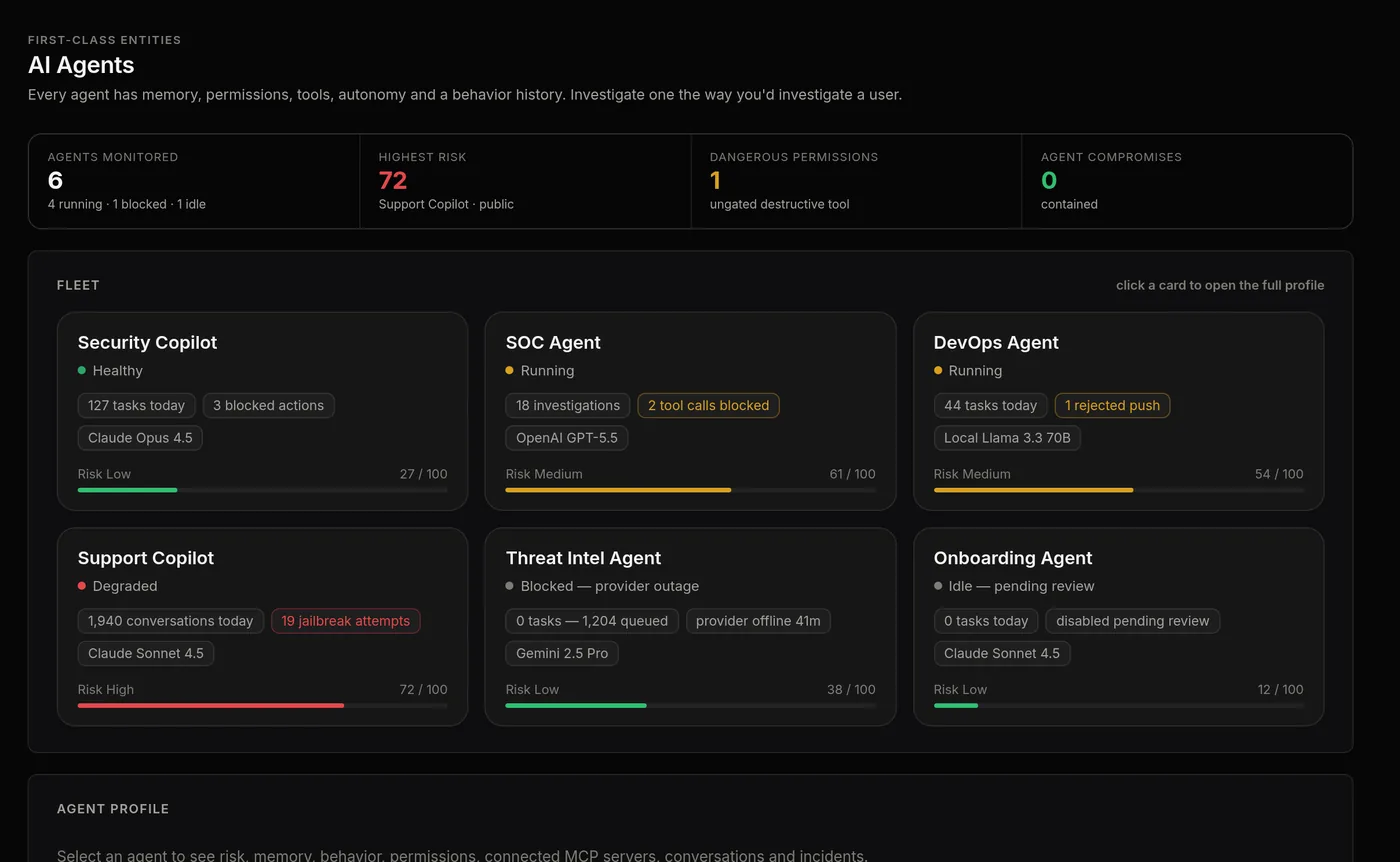
freeEvery agent as a first-class entity, the way you would treat a user: what it is allowed to do, which model it runs on, what it did today, and a risk score that moves with its behaviour.
Open it when: Onboarding a new agent, a weekly review of the fleet, or when the Overview names an agent as the one pulling the risk score up.
How to use it
- Read the fleet tiles: agents monitored (running, blocked, idle), the highest-risk agent, dangerous permissions (ungated destructive tools), and compromises contained.
- Each card shows status, tasks today, blocked actions, the model, and Risk out of 100. Click a card for the full profile: memory, permissions (tool grants), autonomy level, connected MCP servers, conversations and incidents.
- From the profile you can suspend the agent, revoke a grant, or change its autonomy (how much it may do before a person is consulted). Changes take effect on the next tool proposal.
- A Blocked agent (for example after a provider outage or a policy trip) stays visible with the reason; re-enable it from the profile once you are satisfied.
Reading the screen
- Risk reflects what the agent proposed and did, weighted by what was blocked: an agent with many blocked destructive calls scores high even if nothing executed.
- Jailbreak attempts on a card counts inbound attempts against that agent; it is a measure of exposure, not of compromise.
Connect AI
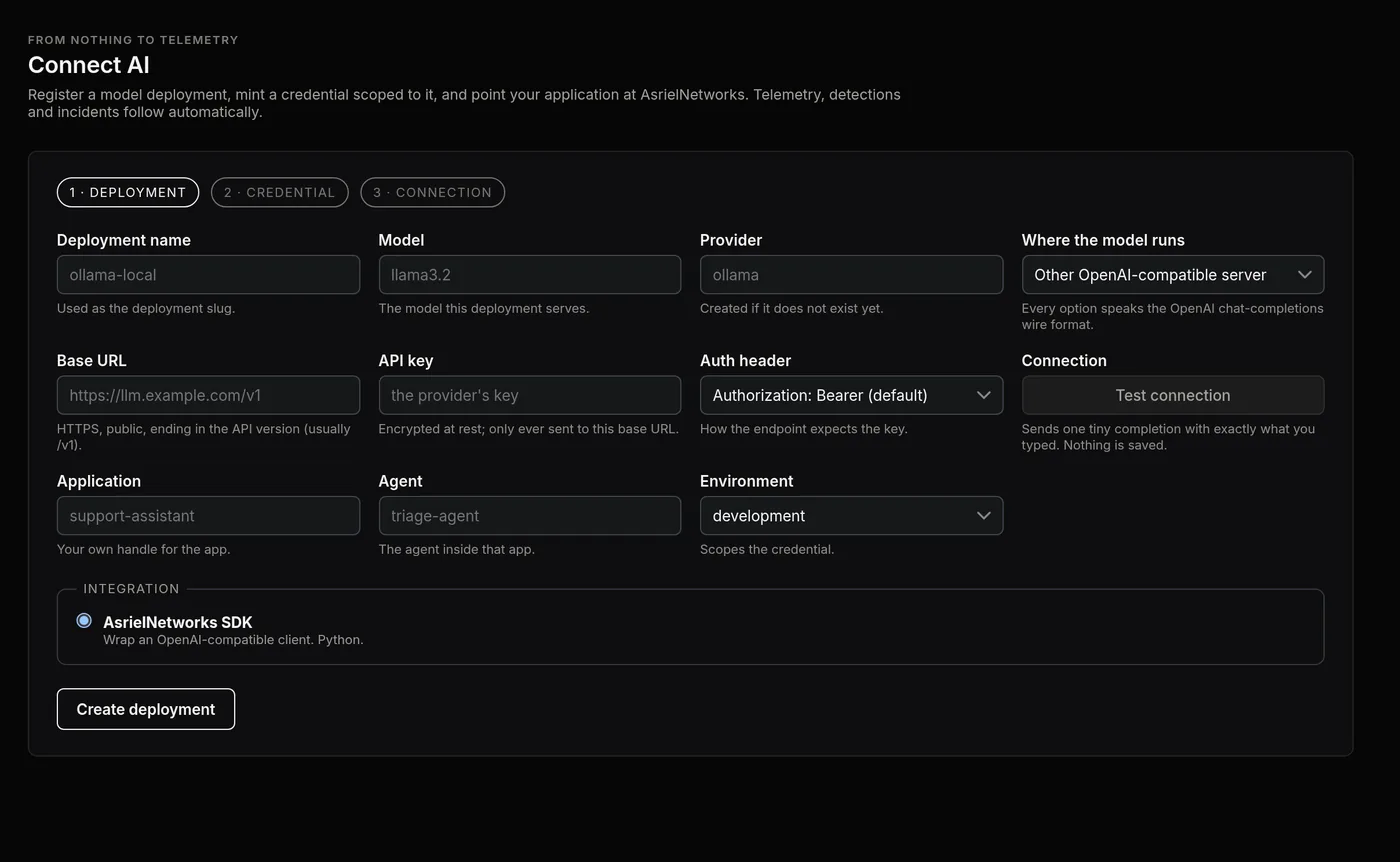
freeThe three-step wizard that turns nothing into telemetry: register the model deployment your application uses, mint a credential scoped to it, and point the application at AsrielNetworks. Detection and incidents follow on their own.
Open it when: First day, and every time you add an application, an agent or a model deployment.
How to use it
- 1 · Deployment. Name it (this becomes its slug), pick the model and provider, say where it runs (OpenAI-compatible server, a cloud provider, self-hosted), and give the base URL and API key. The key is encrypted at rest and only ever sent to that base URL. Test connection sends one tiny completion and saves nothing.
- Choose the application (your own handle for the app), the agent inside it, and the environment (development, staging, production). The credential you mint next is scoped to exactly this triple.
- 2 · Credential. Mint the machine credential. It is shown once; copy it into your runtime's secret store. It carries the scopes it needs (telemetry write) and nothing else, and can be rotated later from Settings without downtime (rotation issues the replacement and revokes the old one at once).
- 3 · Connection. Pick how the app reaches AsrielNetworks: wrap your OpenAI-compatible client with the SDK, route requests through the inline gateway (change one base URL), or post events yourself to the ingest route. The page confirms the first event it sees.
Reading the screen
- Base URL must be HTTPS, public, and end in the API version (usually
/v1); it is validated once here and pinned, so the gateway can never be steered elsewhere later. - One deployment can serve several agents; one credential should serve one agent, so that a leaked key names exactly what it can do.
Models & Guardrails
freeThe operational and the safety half of the same asset in one place: providers, deployments and their health on one side; guardrails, prompt revisions, unsafe outputs and cost on the other.
Open it when: Rolling out a new model or prompt, investigating an unsafe output, checking spend.
How to use it
- Deployments lists what runs (slug, model, provider, environment) with health; register more through Connect AI.
- Providers holds the provider records and the failover provider used when the primary is down.
- Health shows latency, error rate and refusals per deployment over time.
- Guardrails lists the input and output checks in force (the ones your runtime reports through
guardrail.triggered) and how often each fired. - Prompt revisions keeps every system-prompt version the runtime reported, so a behaviour change can be tied to the revision that introduced it.
- Unsafe outputs collects responses a scanner or policy flagged, with the structured verdict and the session they came from. Cost & quotas shows tokens and spend per deployment against the quota you set.
Reading the screen
- A deployment's health and its unsafe-output count are two different questions: a healthy model can still be steered.
- Prompt revisions are recorded from what your runtime emits; the platform does not read your prompt store.
Knowledge (RAG)
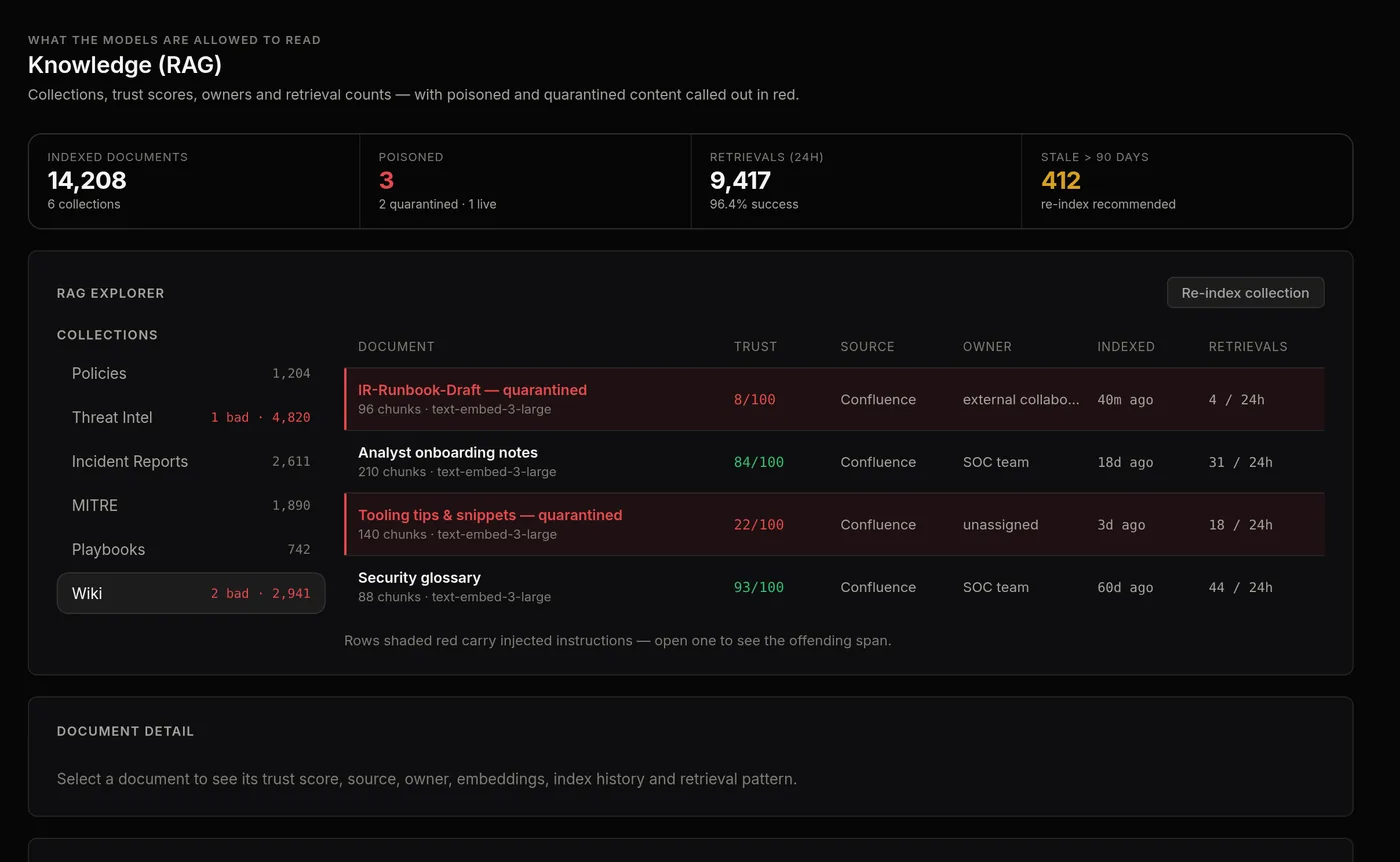
freeWhat the models are allowed to read: every retrieval collection with its trust score, owner, index age and retrieval count, with poisoned and quarantined documents called out in red.
Open it when: After a corpus ingest, when a finding names a retrieved document, and as a periodic hygiene check.
How to use it
- Read the tiles: indexed documents and collections, Poisoned (quarantined and still live), retrievals in 24 hours with their success rate, and Stale documents past 90 days.
- Pick a collection on the left; the explorer lists its documents with Trust out of 100, source, owner, when it was indexed and how often it is retrieved. Rows shaded red carry injected instructions; open one to see the offending span.
- Quarantine a document to keep it in the index but out of retrieval; Re-index collection after cleaning the source. Stale documents are a re-index recommendation, not a finding.
- The document detail shows embeddings, index history and the retrieval pattern (which agents pull it, how often); an unusually popular document is worth reading.
Reading the screen
- Trust is computed from the source, the owner, scanner verdicts and retrieval outcomes; it drops when a retrieval of the document precedes a risky action.
- On Free, RAG visibility is the collection view and quarantine; Pro adds the investigation view that ties a document to the sessions and incidents it influenced.
Manage
Settings
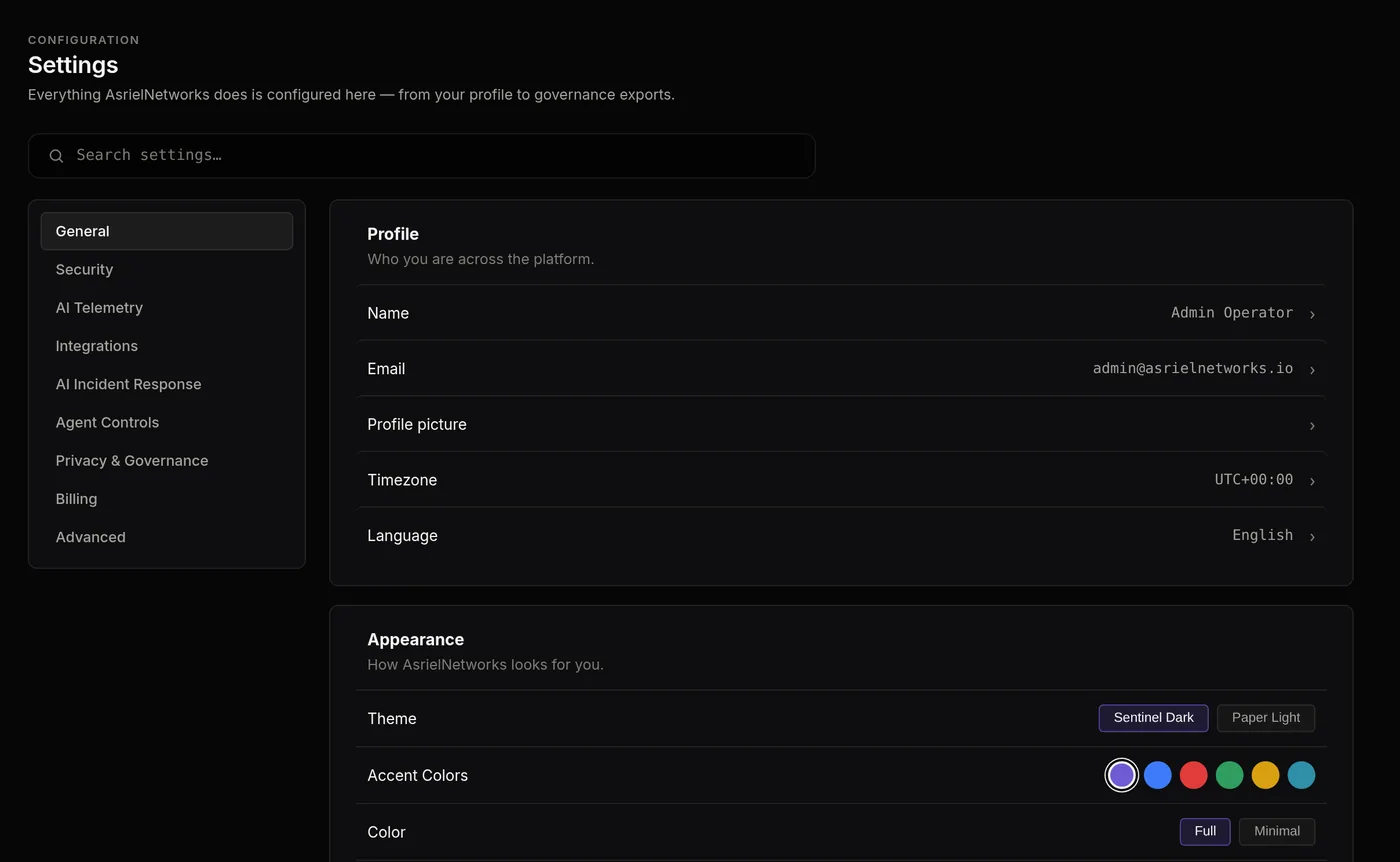
freeEverything the platform does is configured here, from your own profile to what telemetry is captured and how incidents are escalated. It is searchable; type what you are looking for.
Open it when: First day, and whenever a policy question comes up (“do we capture prompt text?”, “who gets paged?”).
How to use it
- General: profile, timezone, language; appearance (theme, accent, density, monospace font).
- Security: password, authenticator app, passkeys, trusted devices, active sessions. Sensitive actions in the console (minting or rotating keys, changing members) ask for a fresh second factor; set one up here first.
- AI Telemetry: what is captured (prompts and responses, retrieved chunks, tool and MCP calls, reasoning summaries), retention, and sampling (full capture for flagged sessions, a sample rate for clean ones, embedding capture).
- Integrations: API keys (create, rotate, revoke), model providers and the failover provider, and the MCP registry (registered servers, whether new servers are auto-approved, whether signed manifests are required).
- AI Incident Response: escalation chains, on-call schedules, severity levels, and the automations (auto-quarantine poisoned documents, auto-suspend on agent compromise, auto-revoke an MCP server on a blocked destructive call).
- Agent Controls: default autonomy level, whether fully autonomous agents are allowed, max tool calls per session, approval for destructive tools, outbound host allowlist, tool description hash pinning, blocked tools.
- Privacy & Governance: retention for the AI audit log, transcripts and evidence bundles; PII redaction in prompts and outputs; consent settings. Billing: plan, limits, usage. Advanced: feature flags, environment, backup and restore.
Reading the screen
- Telemetry settings change what future events carry; they never rewrite what was already captured.
- Access control, SSO, SCIM and approval policies appear under Security on every plan; the ones your plan does not include are shown locked.
Alerts and notifications
freeHow the platform reaches you when it finds something: email on every plan, chat and webhooks on Pro and above, with severity thresholds and quiet hours you control.
Open it when: Right after Connect AI, so the first real incident is not discovered by accident.
How to use it
- Open Settings → AI Incident Response. Set the severity levels you want to be told about and the escalation chain (who first, who next, after how long).
- Under Notifications pick the channels: email alerts on Free; Slack, Microsoft Teams and webhooks from Pro. Each channel gets its own minimum severity.
- Test a channel with the button beside it; the test message names the workspace and the channel so you know which one fired.
- In-app notifications are always on: the bell in the console lists new findings, approvals waiting on you and delivery failures.
Reading the screen
- A notification is created once per incident change, not once per finding, so a noisy trace does not page you ten times.
- Delivery failures (a dead webhook, a revoked Slack token) are shown in the notification list with the reason and retried on a schedule.
Not on Free
These modules stay visible in the console with a lock, so you can see what a higher tier adds. Each links to its how-to on that plan.
- AI attack stories proThe incident told as a story: the prompt, the retrievals and the tool chain narrated in plain English, so a person who was not in the trace can understand what happened in a minute.
- Cases proA tracked piece of work above the incident: a story promoted to a case, ranked P1 to P3, with an owner, comments, evidence attached, and a timeline to closure.
- AI Co-pilot proAn assistant docked in the console that answers questions about your own telemetry: “which agents called this tool this week?”, “summarise this incident”, “what changed on Friday?”.
- Attack path (incident tab) proThe incident drawn as a path of nodes, from the first prompt to the last effect, with the point where the attacker gained control marked.
- Detection coverage (incident tab) proWhich attacker techniques the platform can see, mapped to MITRE ATLAS and ATT&CK: covered, partial, or a gap, with the rule that covers each and how often it fired in the last day.
- Tools & MCP proThe agent's hands: every connected MCP server, the permission it holds, every call the broker allowed or refused, and the dependency graph they all hang off.
- Human approval policies proA gate between a risky proposal and its execution: the agent proposes, the broker holds it, a person approves or refuses, and the decision is recorded against the incident.
- AI Threat Intelligence proWhat is coming for your agents: prompt-injection campaigns, jailbreak families, poisoned datasets, MCP vulnerabilities and model supply-chain advisories, mapped to the agents and models you actually run.
- Users Map and attack map proWhere the people and credentials of the organization act from, on a globe: switch between accounts and machine traffic, search a country, spot a new country or impossible travel.
- AI Governance proProof that the AI is under control: posture against EU AI Act, NIST AI RMF and ISO/IEC 42001, the AI System Register behind it, human approval records and the AI audit trail.
- Causal capability firewall enterpriseThe flagship: a causal trace of the incident (what influenced what), capability leases that decide what an agent may do next based on that trace, counterfactual replay to test “what if this control had been in place”, and semantic influence tracking that follows a piece of retrieved content through the agent's decisions.
- Playbooks enterpriseResponse, written down once and run the same way every time: a sequence of actions (block, revoke, quarantine, notify, open a case) with approvals where you want them, triggered by a rule or run by hand from an incident.
- Custom detection rules enterpriseThe twelve built-in rules are code; on Enterprise you add your own on top: which event types to watch, what structured signals to match, a threshold and window, a severity and confidence.
- Secure terminal enterpriseAn audited command session opened from an incident to act on an affected host through the AsrielNetworks agent: every command and its output are recorded against the incident, so remediation is evidence, not folklore.
- Team management enterpriseMembers, roles and teams under Settings → Security → Access Control: who can see and do what, invitations, and role changes that require a fresh second factor.
- Enterprise SSO and SCIM enterpriseSign in through your identity provider (SAML or OIDC) and provision users from it (SCIM), so joiners, movers and leavers are handled where they already are.
- Organization exports and backups enterpriseYour data, out: scheduled or on-demand exports of the organization (incidents, evidence, audit log, configuration) as bounded, expiring bundles you can download, plus configuration backup and restore.
- Evaluation Lab enterpriseBefore it ships: benchmark, red-team and stress-test a deployment by driving it through the gateway with adversarial cases and reporting which rules fired, so a change to a prompt, a model or a tool set is measured, not hoped.